Turn every watt
into trusted intelligence
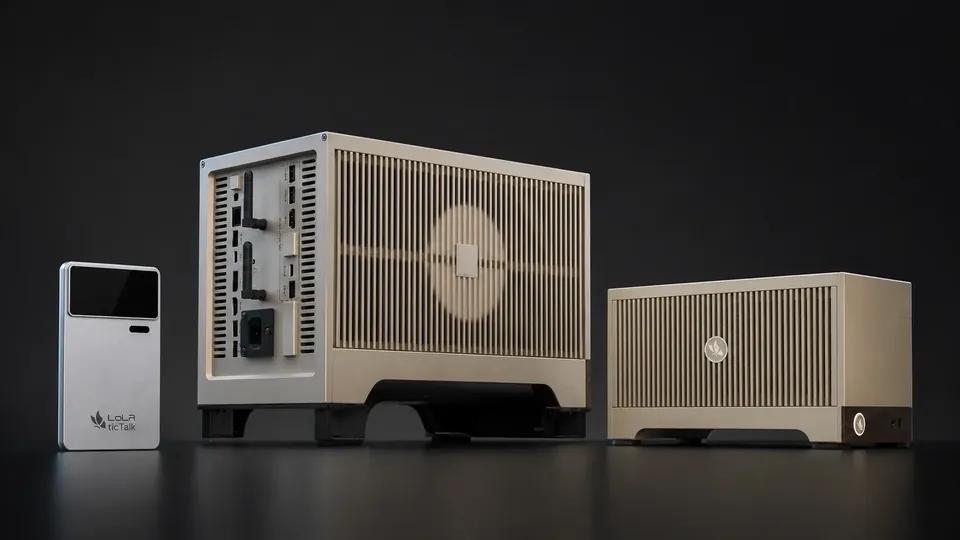
A Trusted Foundation starts at the physical layer: data stays on the device, inference runs locally, and the enterprise owns its computing resources. That is why LoLR.AI develops its own on-device hardware. With limited power and space, compute must be used efficiently. Alongside general-purpose computing, FPGA—field-programmable gate arrays, hardware customizable for specific tasks—and dedicated accelerators distribute workloads by task type. The LoLR distributed compute network then organizes devices, edge, and cloud into a schedulable, auditable whole.
- CPULogic and scheduling: complex decisions, system scheduling, and small unstructured tasks.
- GPUParallel inference: large-model inference and parallel matrix operations provide core AI computing power.
- FPGA · Dedicated accelerationPipeline acceleration for frequent tasks such as memory management, OCR, and encryption significantly reduces power consumption.
- Coordinated schedulingDistribute workloads by task type; every device runs the same LoLR.AI OS and Skills system.
Explore the full LoLR HPCs lineup→
CPULogic & SchedulingRule evaluation · System scheduling · Small unstructured tasks
GPUParallel inference accelerationLarge-model inference · Parallel matrix operations · Core AI computing
FPGADedicated hardware accelerationFPGA and dedicated accelerators · Memory management · OCR · Encryption
General-purpose computing for frequent tasks
1×
Dedicated hardware acceleration
10×
Energy efficiency comparison for frequent tasks including memory management, OCR, and encryption, measured under laboratory conditions. Overall system performance depends on the models and operating environment.
Organizing compute across devices and cloud
A single device has limited compute, while enterprise tasks span individuals, departments, and institutions. The LoLR distributed compute network brings portable and desktop devices, internal servers, and authorized cloud resources into one network, with heterogeneous processing within nodes, unified scheduling across the network, and secure links controlling transfers between nodes.
Heterogeneous compute nodesWithin each node, CPUs handle logic and scheduling, GPUs handle parallel inference, and FPGA and dedicated accelerators handle frequent tasks such as memory management, OCR, and encryption.
Distributed schedulingSelect device, edge, or cloud execution by data sensitivity, latency, model size, and cost; orchestrate multiple organizational devices according to concurrent demand.
Secure linksDevice authentication, end-to-end encryption, access control, and complete logs. Raw data stays at its originating node; tasks and conclusions move between nodes.
Energy-efficient distributed computingFrequent tasks run on nearby dedicated device hardware, large-model inference runs on department and institution nodes, and authorized cloud resources meet elastic demand. Compute is allocated for energy efficiency.